Docling, the library I tested that blew my mind
Published on
I conducted a proof of concept with the Docling library, validating its high effectiveness in the automated conversion of PDFs and images to optimize the creation of knowledge bases for AI.
In the last few days, I've been exploring ways to transform documents into a format optimized for indexing and search. That's when I came across the Docling library, and I have to say: I was impressed by its ease and precision in file conversion.
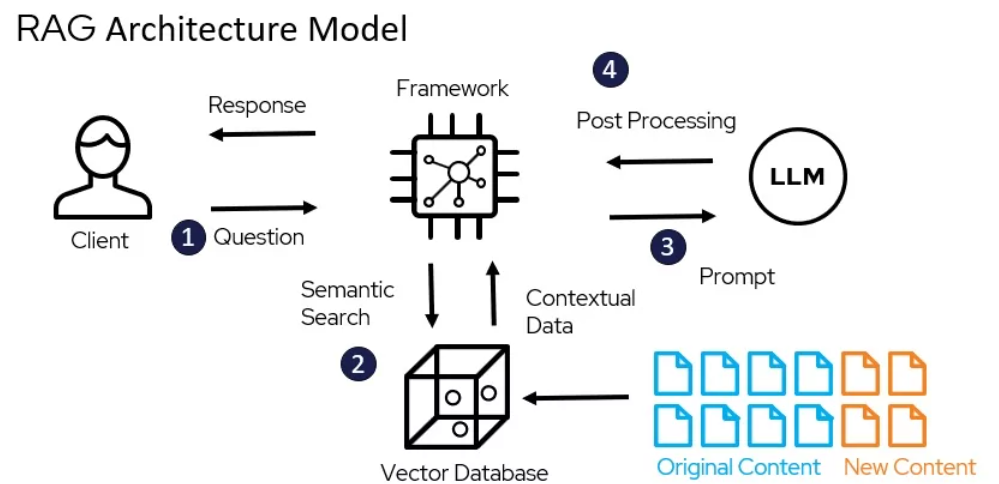
Before talking about the tests, it's worth providing some context on Retrieval-Augmented Generation (RAG). RAG is an approach that combines large language models (LLMs) with information retrieval systems. Basically, instead of relying solely on the data the model already knows, it searches for information in external sources, such as indexed documents, to provide more accurate and up-to-date answers. For this to work well, it is fundamental to have a well-structured database optimized for rapid information retrieval – and that is where the importance of efficient document conversion comes in.
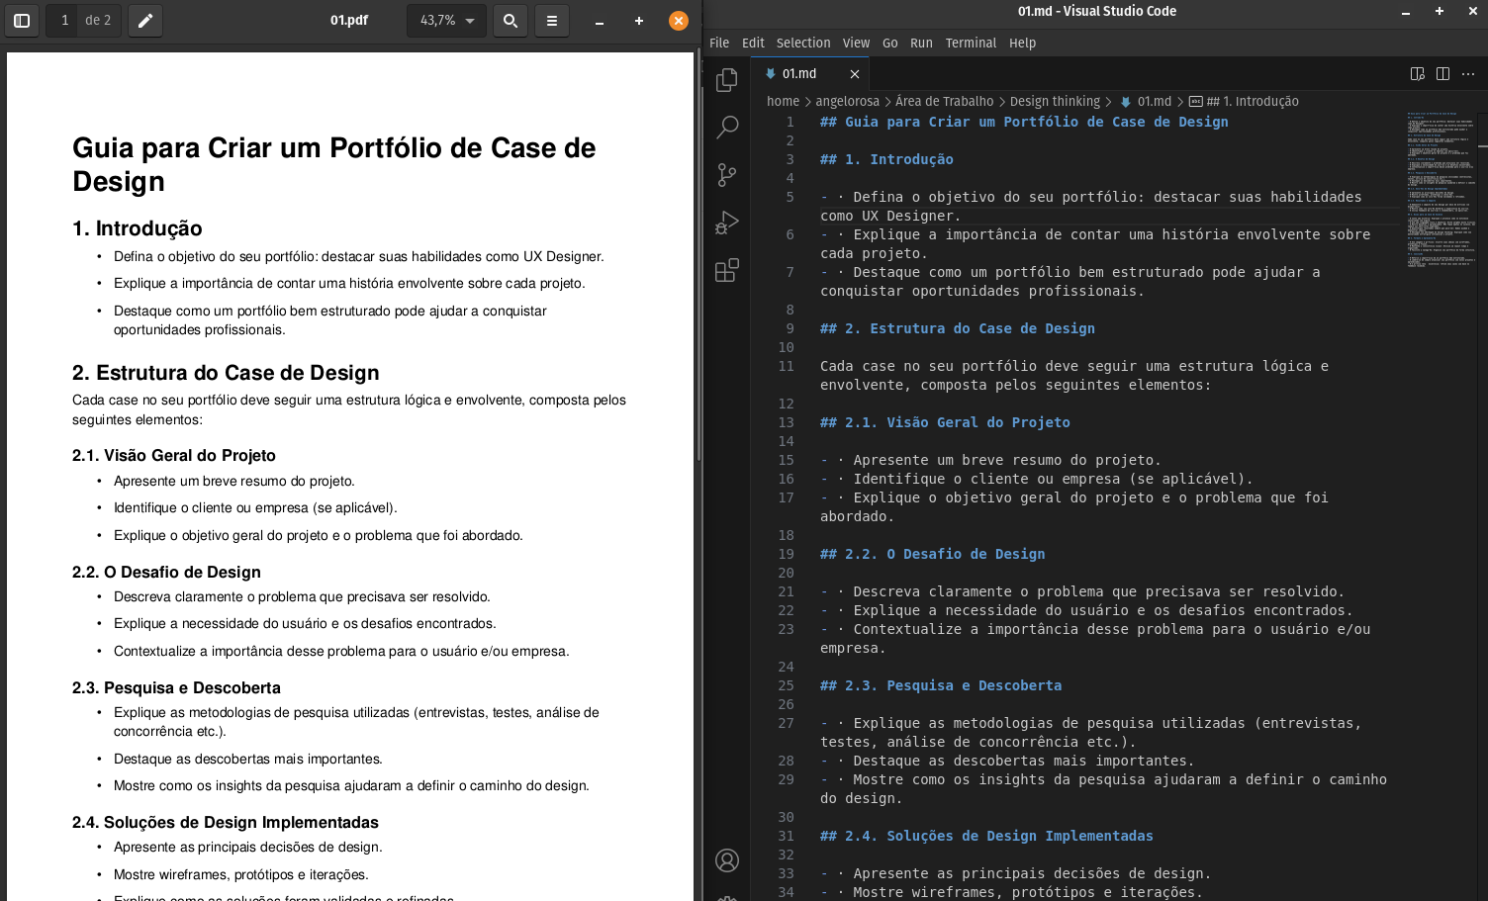
My first test was with a text-only PDF. The result? Perfect. The library read all the information correctly and transformed the content into a structured Markdown (.md) file faithful to the original. The level of accuracy surprised me, especially because many conversion solutions end up losing formatting or introducing errors in the process.
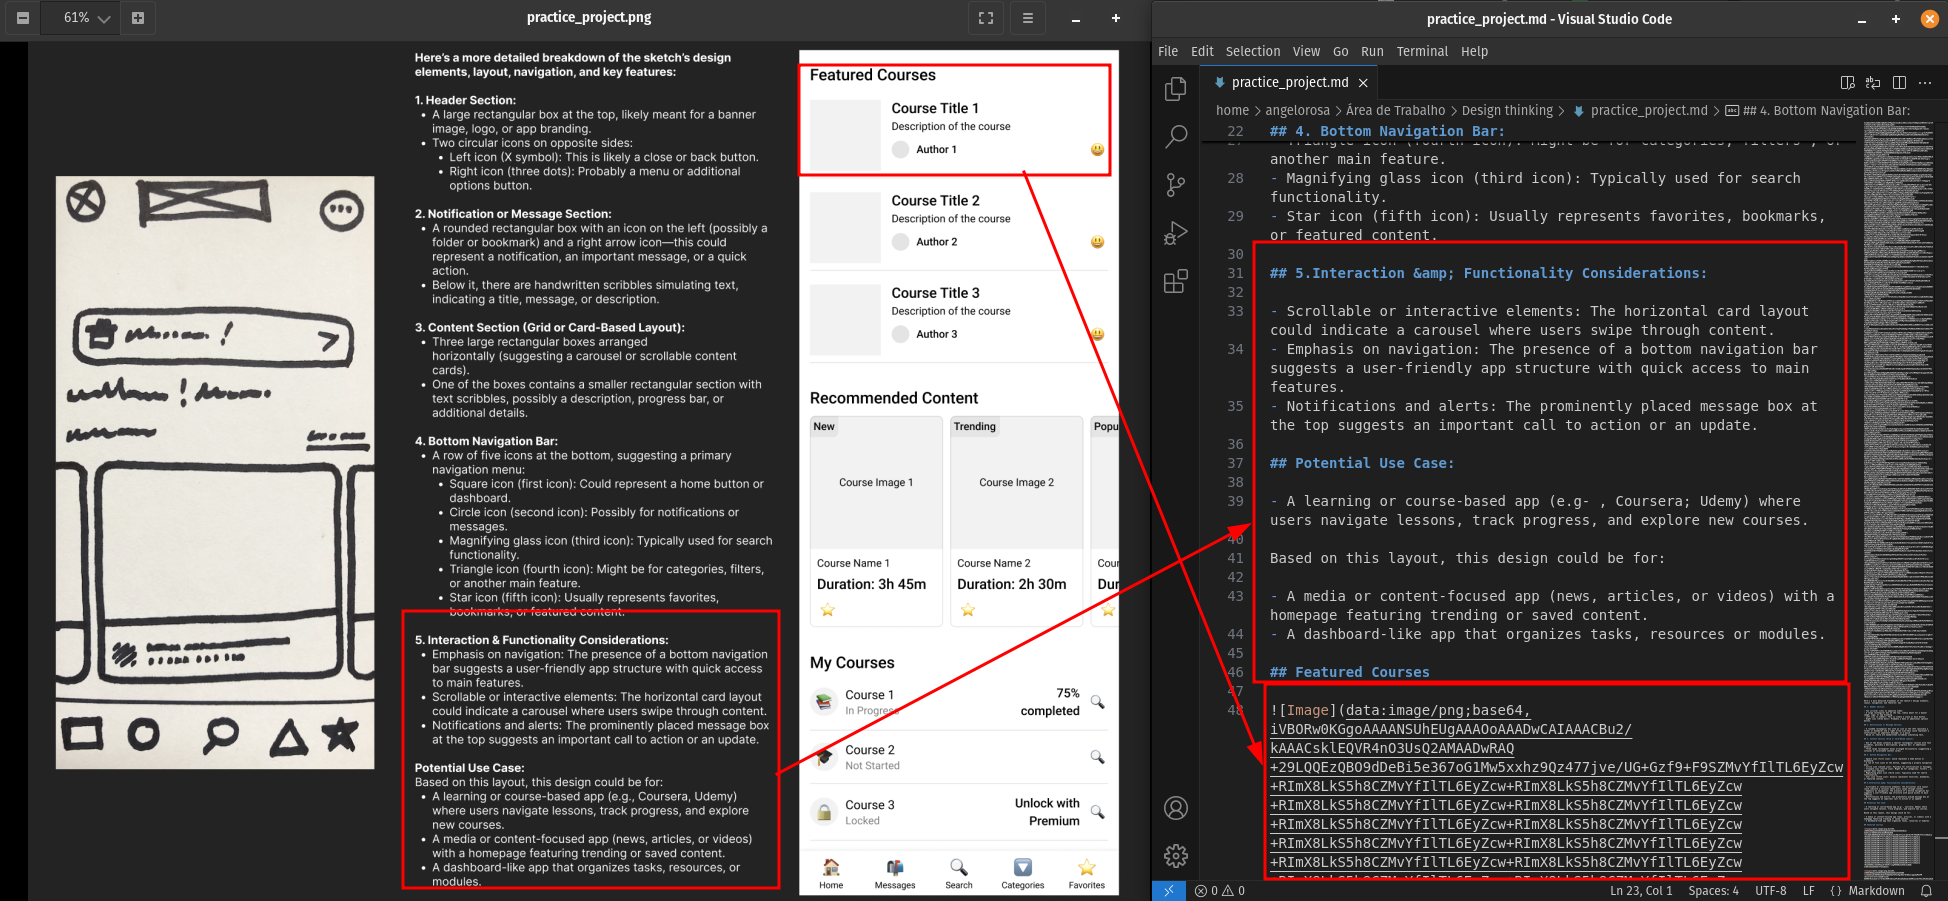
I then decided to raise the level of the test and threw in a PNG containing text and images for conversion. Once again, Docling delivered an excellent result: it extracted the text and converted it to Markdown, keeping the structure organized, and, even better, embedded the images into the file using base64. This means the generated MD file became completely portable, without depending on external links or additional folders to store the images.
The impact of this is huge. Imagine a tool based on this library that allows for batch conversion of all a company's documents. With this, it would be possible to transform various files (PDFs, images, and other formats) into Markdown documents ready to be indexed in a vector database. This would open up space to implement intelligent search systems based on language models (LLMs), allowing previously scattered information to be retrieved quickly and efficiently.
This experience made me see the potential for automation in document processing and how technologies like this can optimize workflows. If you are also exploring this universe, it is well worth testing Docling and thinking about the possibilities it can open up!
Link to the repository, it's open source: https://ds4sd.github.io/docling/